


Most WordPress sites reach for a plugin the moment they need a contact form. It works, but it is not the only way. You can create forms in WordPress without…
Table of contents
Validate every field against an allowlist before anything else. Then clean only the values you have to accept exactly as typed, encode on the way out, and bind database values with parameterized queries. None of this counts if it only happens in the browser, so it all runs on the server.
Validation accepts or rejects a submission. Sanitization rewrites it, escaping or stripping dangerous characters and markup along the way. Hidden fields, cookies and headers get the same treatment as the visible inputs.
OWASP’s Input Validation Cheat Sheet keeps validation apart from the defenses that handle data afterward, which means parameterized queries for SQL and context-aware output encoding for cross-site scripting. Its SQL Injection Prevention Cheat Sheet calls escaping all dynamic input strongly discouraged. So the heavy lifting sits with output encoding and parameterized queries, and cleaning the input only backs them up.
How does user input sanitization differ from validation and output encoding?
Sanitization cleans, escapes or removes dangerous characters and markup from submitted form data, so nothing in it can run as code in a browser, a database query, a shell command or a file path.
Validation just says yes or no. Sanitization changes the value.
Output encoding gets mixed up with the other two more than anything else. It converts data into a safe form at the moment the application displays it.
| Control | What it does | When it runs | What it cannot do |
|---|---|---|---|
| Validation | Accepts or rejects input against rules (type, length, format, allowlist) | On receipt, before processing | Make free text safe to render |
| Sanitization | Strips, escapes or rewrites unsafe characters and markup | After validation, before use | Replace output encoding or parameterized queries |
| Output encoding | Converts special characters for one specific destination | At render time, per context | Remove malformed or unwanted data |
OWASP draws the same line. The Input Validation Cheat Sheet describes validation as checking whether data meets the application’s requirements, then points to parameterized queries and output encoding for what comes after. The XSS Prevention Cheat Sheet adds that validation can enforce expected formats but does not replace output encoding or HTML sanitization.
It also favors allowlisting. You define what the application accepts and reject everything outside those rules, rather than trying to recognize every malicious string.
Validation rules come first, field by field, and these best practices for validating form fields cover the type, length and format checks in detail.
In practice the order runs like this: validate against an allowlist, sanitize whatever has to be accepted as typed, and encode at output for each destination.
Everything in the HTTP request sits outside the trust boundary, not only the visible form fields. Hidden fields, cookies, HTTP headers and query strings all arrive from the client. OWASP’s Input Validation Cheat Sheet extends the same rule to internal APIs, partner feeds, queues and stored records when their data crosses a trust boundary.
Which attacks does sanitizing form input stop, and which need another control?
Sanitization is the primary control for exactly one case, which is cross-site scripting through submitted HTML. SQL injection, command injection and path traversal each lean on something else.
- Cross-site scripting (CWE-79) is handled mainly by output encoding. Sanitization applies when users must submit HTML, and a Content Security Policy backs both up.
- SQL injection (CWE-89) calls for parameterized queries. OWASP’s SQL Injection Prevention Cheat Sheet lists prepared statements first and marks escaping all dynamic input as strongly discouraged.
- For OS command injection (CWE-78), keep user data away from the shell, and allowlist whatever has to reach it.
- Path traversal (CWE-22) is about file names. Allowlist names and extensions, and generate the stored file name on the server.
MITRE’s 2025 CWE Top 25 keeps cross-site scripting at #1 and moves SQL injection up one place to #2.
OWASP moved injection from #3 to #5 in its Top 10:2025, yet the category still had the greatest number of CVEs of any category, across its 37 CWEs. A lower rank did not mean fewer vulnerabilities.
TalkTalk shows what skipping the primary control costs. Between 15 and 21 October 2015, an attacker used SQL injection against three vulnerable web pages and accessed the personal data of 156,959 customers. In October 2016 the ICO fined the company GBP 400,000, and noted that TalkTalk had already suffered SQL injection attacks through the same vulnerability in July and September 2015.
A Content Security Policy sits behind the code-level controls, not in front of them. The W3C specification says CSP is not intended as a first line of defense against content injection vulnerabilities. It is best used as defense-in-depth, and it does not replace careful input validation and output encoding.
A web application firewall filters known attack patterns at the network layer. It buys time on legacy code but does not fix the code, and OWASP warns that a WAF cannot reliably prevent all XSS.
Client-side and server-side sanitization: what each layer covers
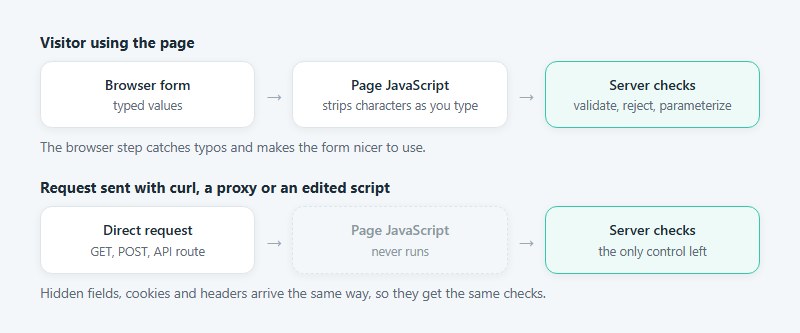
Only server-side code counts as a security control. Client-side filtering makes the form nicer to use and gives an attacker nothing to respect.
Client-side checks
A common tutorial pattern strips unwanted characters while the user types, using a regular expression on the input event. Typos get caught instantly, fewer submissions bounce, and cleaner data reaches the server.
All of that is usability. A request sent with curl, a proxy or an edited script never touches the page’s JavaScript, so none of the filtering runs.
Where each layer sits in a validation flow is laid out in this comparison of client-side and server-side form input validation.
Server-side checks
OWASP’s Input Validation Cheat Sheet says to validate on the server even when the browser checks the same fields, because client-side validation can be bypassed. An attacker who disables scripting or routes requests through a proxy walks right past browser-side JavaScript checks.
The same pipeline has to cover every entry point, including GET parameters, API routes and the mobile app. The usual slip is a routine that protects the POST form and misses the GET route. OWASP Cornucopia (card VE8) describes this bypass. Centralized sanitization routines that are not applied to every input channel can be avoided by submitting data through a different one.
Input time vs output time
Sanitizing and encoding on input locks one destination’s encoding into the stored value. HTML-escaped text shows up as & in a plain-text email or a CSV export, and the whole approach breaks the moment the same value reaches a second context.
Storing the original and encoding on output works better. One stored value can then serve HTML, attributes, JSON and email, which matters because browsers parse HTML, JavaScript, URLs and CSS differently, so the right method depends on the destination (OWASP XSS Prevention Cheat Sheet).
Validate on the way in, use parameterized queries for storage, encode on the way out.
Output encoding by context: HTML, attribute, JavaScript, URL and CSS
The destination decides the encoding. HTML entity encoding fits the HTML body, and every other context needs its own method.
In an HTML body, the input <script>alert(1)</script> becomes <script>alert(1)</script> and the browser prints it as text instead of running it.
- For the HTML body and attributes, use HTML entity encoding and put every attribute value in quotes. In JavaScript, textContent is a safe sink because it creates a text node without parsing HTML. It does not encode anything, so pass it the original text and never pre-encode the value. Attributes that take JavaScript, such as onclick, stay unsafe even when encoded, so register handlers with addEventListener() instead.
- Inside JavaScript, insert string data only within a quoted string, using an encoder that also protects the enclosing HTML script context. Skip eval() and string arguments to setTimeout() or setInterval(). JSON responses go out as application/json, not text/html.
- URLs get percent-encoding on each untrusted parameter value in the %HH format (encodeURIComponent() in JavaScript). When the finished URL goes into an href or src attribute, follow that with HTML attribute encoding, and allow only http and https URLs.
- Never place untrusted data directly into CSS source, including selectors, property names and declaration blocks. For dynamic styling, call element.style.setProperty() with a fixed property name and a value checked against an allowlist for that property.
Some locations resist encoding altogether. OWASP calls them dangerous contexts and says no variable belongs there:
- Directly inside a script block
- Inside an HTML comment
- Directly inside a style block
- As an attribute name or a tag name
OWASP also lists areas that need extra care: callback functions, URLs handled in code, untrusted event handler code such as an entire onclick value, and unsafe JavaScript functions such as eval(), setInterval() and setTimeout().
Where a template engine already encodes by default, leave that on and add explicit encoding only for the gaps.
Encoding breaks one case, though. A rich text editor needs the markup to survive, and that case calls for an HTML sanitizer instead.
How to sanitize form input step by step
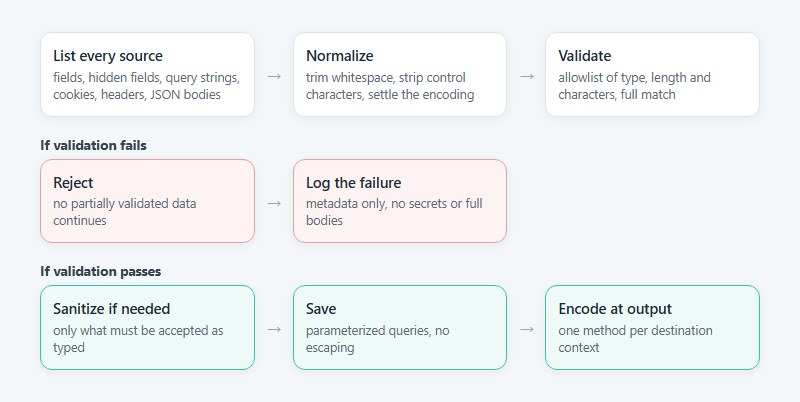
A form goes from submission to display in this order.
- List every input source: form fields, hidden fields, query strings, cookies, headers and JSON bodies.
- Normalize before checking anything. Trim whitespace, strip control characters and settle the character encoding, because OWASP’s LDAP Injection Prevention Cheat Sheet puts normalization ahead of validation. The Input Validation Cheat Sheet adds that normalization is not sanitization and does not replace output encoding.
- Validate against an allowlist of type, length and characters. Match the entire value with a regular expression (OWASP suggests an API such as Python’s fullmatch), cap the length before matching, and avoid patterns with excessive backtracking.
- Reject on failure. OWASP’s REST Security Cheat Sheet says to reject unexpected or illegal content, and the Input Validation Cheat Sheet says not to continue with partially validated data.
- Sanitize only what has to be accepted as typed, with the library built for that content type.
- Save with parameterized queries instead of escaping values for the database.
- Encode at output for the destination context.
- Log validation failures, especially on endpoints that only your own front end is supposed to call. Record the failure and relevant metadata, without secrets or full request bodies.
A rejected field needs a message that names the problem. These examples of form error messages show how other forms word them.
Rules for common field types
- For text and textarea fields, allowlist the character set where the field allows it (a postcode, a username) and cap the length. Leave names and free text unfiltered, so the apostrophe in a surname survives.
- Email and URL fields should be validated instead of repaired. PHP’s FILTER_VALIDATE_EMAIL never alters the input, while FILTER_SANITIZE_EMAIL strips illegal characters and does not check that the result is a real address (PHP manual).
- Accept http and https URL schemes, plus mailto where a link needs it, and reject the rest. A javascript: scheme in an href runs script.
- Don’t keep the visitor’s file name. The OWASP File Upload Cheat Sheet calls for an application-generated name, an extension allowlist, a length limit and no trust in the Content-Type header. In a WordPress form, the file upload field settings hold the allowed file types and the maximum file size.
Number and select fields follow a simpler rule. Cast numbers to the expected type, and require a select value to match exactly one option the form offered.
Sanitization functions and libraries by language
Match the function to the destination context, then check that it is still supported in your version. Two names that fill older tutorials are not.
| Language | Function or library | What it does | Known limit |
|---|---|---|---|
| PHP | htmlspecialchars(), filter_var() | Encodes HTML special characters; filters validate or strip by type | HTML context only |
| Node.js | validator.js, express-validator | trim(), stripLow(), escape() on strings | escape() writes HTML entities into the stored value |
| Python | html.escape(), Django templates | Templates escape < > & and both quote types by default | autoescape off and the safe filter switch it off |
| Java | OWASP Java Encoder | forHtml(), forJavaScript(), forUriComponent() | Encodes only, never cleans markup |
| ASP.NET Core | HtmlEncoder, JavaScriptEncoder, UrlEncoder | Razor encodes variables by default | HtmlString output is not encoded |
PHP changed twice in version 8.1. FILTER_SANITIZE_STRING became deprecated, with htmlspecialchars() as the documented replacement, and htmlspecialchars() switched its default flags from ENT_COMPAT to ENT_QUOTES | ENT_SUBSTITUTE | ENT_HTML401 (PHP manual).
On PHP 8.0 and older, a bare htmlspecialchars() call leaves single quotes alone. That matters for any attribute value wrapped in single quotes.
The Python cleaner bleach is on the deprecated list too. Mozilla marked it deprecated on January 23, 2023, and some projects have moved to nh3.
Field names need an allowlist as much as values do. Rails strong parameters (require and permit) drop every key not listed, and Zod object schemas strip unknown keys by default, with .strict() to reject them instead.
Neither tool makes string content safe to render. The Strong Parameters README adds that untrusted data used for mass assignment outside controllers still needs sanitizing.
How to sanitize rich text and HTML from editors
Pass the editor’s HTML through an allowlist-based sanitizer on the server, and keep the allowlist no wider than the editor’s toolbar. On WordPress, a form plugin’s rich text field can take care of part of this, sanitizing the content on submit and stripping inline scripts.
OWASP’s XSS Prevention Cheat Sheet recommends DOMPurify for this and attaches conditions. Patch the library regularly, and leave the sanitized string alone afterward. DOMPurify’s own README agrees that editing HTML after sanitizing can void the protection.
The ASP.NET Core documentation starts one step earlier. Parsing HTML input can be difficult, and sometimes impossible, so Markdown coupled with a parser that strips embedded HTML is the safer option for rich input.
If the Markdown parser lets raw HTML through, the sanitizer still belongs in the pipeline.
On the server you have a few libraries to pick from.
- DOMPurify, with a window object supplied by jsdom on Node
- sanitize-html for Node, which has per-tag attribute allowlists and limits href, src and cite to http, https, ftp, mailto and tel by default
- HTML Purifier for PHP, with per-element whitelists and standards-aware parsing
- nh3 for Python, a binding to the Rust ammonia library
One configuration trap in sanitize-html: setting allowedTags or allowedAttributes to false lets everything through.
The browser now ships its own sanitizer. Element.setHTML() arrived in Firefox 148 (released February 24, 2026) and in Chrome 146 (Chrome for Developers, March 10, 2026).
Articles from February 2026 list Chrome 146 as still in beta. They predate its stable release, and the sources checked in November 2026, including web.dev’s browser support table, list no Safari implementation.
Native does not mean bug-free. Searchlight Cyber reported two bypasses in Chrome 146’s implementation (an xlink:href case and a javascript: URL case), and both fixes shipped with Chrome 147 on April 7, 2026.
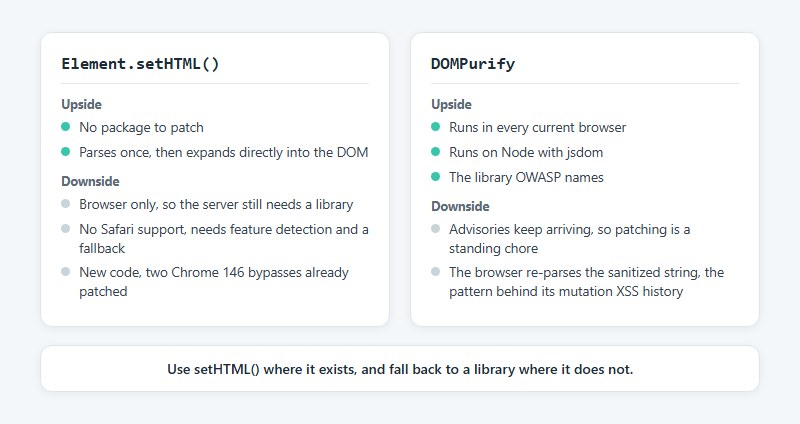
The upside of setHTML() is that there’s no package to patch. web.dev notes that it parses the input once internally and expands the result directly into the DOM. The downsides are real, though. It runs in the browser only, so the server still needs a library, and with no Safari support you need feature detection and a fallback. It’s also new code, with two Chrome 146 bypasses already patched.
DOMPurify has the opposite profile. It runs in every current browser and, with jsdom, on Node, and it’s the library OWASP names. But advisories keep arriving, so patching turns into a standing chore, and the sanitized string gets re-parsed by the browser, which is the pattern behind its mutation XSS history.
Use setHTML() where it exists and fall back to a library where it does not.
When user input sanitization fails
Sanitization breaks down in a handful of predictable ways, and most of them come from trusting it too much.
- Blocklists are guesswork. OWASP warns against trying to recognize every malicious string, and blocking apostrophes, for example, rejects legitimate names without making a database query safe.
- Over-stripping removes data people actually need. eSecurity Planet (Julien Maury, 2025) warns that sanitization can inadvertently remove necessary data and gives a false impression of security, because stripping characters and tags is only one layer of checking.
- Parser mutation happens when the browser parses sanitized HTML differently the second time. DOMPurify’s advisory record shows how often that happens.
- Order mistakes are the quiet one. OWASP’s File Upload Cheat Sheet requires validation after the file name is decoded, and editing a string after the sanitizer ran voids the result.
Three DOMPurify advisories show the range of parser mutation:
- CVE-2020-26870, before 2.0.17: a serialize-parse round trip did not return the original DOM tree
- CVE-2025-26791, before 3.2.4: an incorrect template literal regular expression when SAFE_FOR_TEMPLATES is set
- GHSA-h8r8-wccr-v5f2, before 3.3.2 (March 27, 2026): mutation XSS when sanitized HTML is re-inserted into a new parsing context through innerHTML
A sanitizer is code that parses attacker-controlled markup, so it is an attack surface of its own. That’s the case for keeping it out of every field that does not need it.
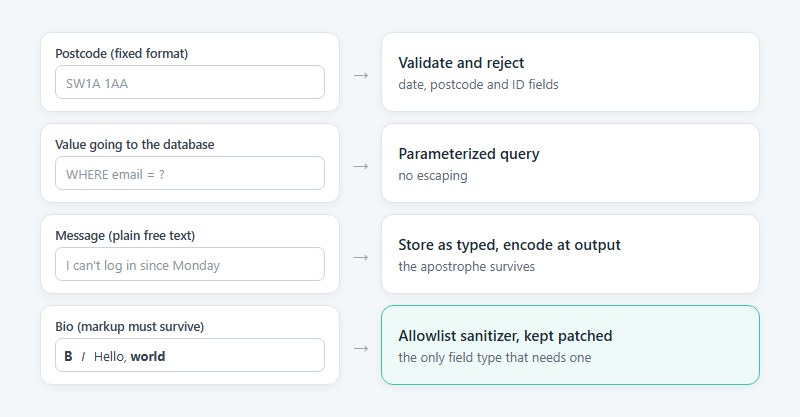
To pick a control for a given field, take the first line below that matches it.
- Fixed format (date, postcode, ID): validate and reject
- Database value: parameterized query, no escaping
- Plain free text: store as typed, encode at output
- Markup that must survive: allowlist sanitizer, kept patched
Free Email Regex Validator for Forms
User Input Sanitization FAQ
Is an HTML5 email or number input type enough?
Not on its own. Input types such as email and number validate in the browser only, and any request sent without the page skips them. Repeat every check on the server, because the browser’s rules are a convenience for honest visitors.
Does framework auto-escaping make sanitization unnecessary?
It covers one context, and that’s the catch. Django templates, Razor and similar engines encode variables for the HTML body by default, but OWASP notes that problems occur when escape hatches are used, such as React’s dangerouslySetInnerHTML without sanitizing or Angular’s bypassSecurityTrust functions.
Values placed in JavaScript, unquoted attributes or output marked as safe fall outside the default encoding.
How do you sanitize a JSON request body in an API?
Validate the body against a schema and reject whatever does not fit. Zod, JSON Schema and similar tools check types and lengths. Zod can drop or reject unknown keys, and JSON Schema can reject them once additional properties are configured, so only expected fields reach your code.
Encode string values later, where they are rendered.
Should passwords be sanitized?
No. Stripping characters changes what the user typed and shrinks the character set. Hash the value with a dedicated algorithm such as Argon2id or bcrypt, and never render it back. A password field in a WordPress form masks the value and saves it in a hashed format.
How can you test that sanitization works?
Feed the form known attack payloads and assert on the output. Cover each context (HTML body, attribute, JavaScript, URL) with strings such as an img tag carrying an onerror handler.
Then add an automated scanner and manual testing, as eSecurity Planet recommends.
Where to Start on a Form Already in Production
On a live form, fix user input sanitization problems in order of damage, not effort. Parameterize every query that touches submitted values first. Encode at each render point, per context. Allowlist rules per field and a sanitizer for markup fields come after that.
Field rules go last because they reject data the form accepted before. Stored records and returning visitors will hit new errors, so that change needs a test pass on existing values and a release note.
Sanitizer libraries need an owner. Subscribe the package to automated dependency alerts, so a new advisory reaches the team the day it publishes.
Verified November 2026: a Safari release of setHTML() would remove the browser-side fallback library, while the server-side sanitizer stays.